外观
本页尚未翻译
本页内容仍为英文原文,源自官方文档 integrations/lerobotdataset。中文翻译正在分批进行中。
LeRobotDataset
Train LeRobot policies straight from object storage, and curate, search and visualize robotics datasets as Lance tables.
LeRobot is HuggingFace's open-source robotics stack. Since lerobot#4363 it reads Lance datasets natively, and lerobot-lancedb wraps that into a ready-made dataset class for video features: same items, same training pipeline. Image-backed features are not supported -- re-encode them as video first.
What you get:
- Train from object storage while keeping your GPUs fed. Lance reads random frames straight from S3, GCS, the HF Hub or HF Storage Buckets, fetching only the bytes each batch needs, so every batch is a global shuffle: any frame, from anywhere in the dataset. In the table below (samples/s, 8 workers, batch 64), Lance and upstream local both draw every batch from the whole dataset. Upstream streaming does a reservoir shuffle, reading the dataset in order and drawing each batch from a pool of recently seen frames, so those two columns are not the same job:
| dataset | window shuffle, Lance from object store | window shuffle, upstream streaming from the Hub | Lance (object store) vs upstream streaming | RAM, Lance | RAM, streaming | global shuffle, Lance from object store | global shuffle, upstream from local NVMe | Lance (object store) vs upstream (local NVMe) |
|---|---|---|---|---|---|---|---|---|
| DROID | 904 | 478 | 1.9x | 8 GB | 122 GB | 257 | 224 | 1.1x |
| roboturk | 778 | 152 | 5.1x | 6 GB | 9 GB | 1,074 | 983 | 1.1x |
| aloha_mobile_cabinet | 772 | 51 | 15.2x | 9 GB | 30 GB | 693 | 573 | 1.2x |
| koch_pick_place_5_lego | 701 | 54 | 13.0x | 8 GB | 15 GB | 876 | 526 | 1.7x |
| pusht | 5,340 | 648 | 8.2x | 3 GB | 7 GB | 5,508 | 4,224 | 1.3x |
| aloha_static_cups_open | 597 | 45 | 13.2x | 10 GB | 38 GB | 575 | 483 | 1.2x |
The shuffle window is 0.05% of the dataset, at least 5,000 frames: 5,000 on the small sets, 13,815 on DROID. Streaming DROID at that window in upstream default needs 122 GB, so those two runs used a 256 GB machine with the same decode speed. The DROID pair is noisy: Lance 684 and 1,124, streaming 303 and 653.
Same batches: Lance from an object store is 1.9x faster than upstream streaming on DROID and 5x to 15x on the other datasets, with 8 GB of RAM against 122 GB on DROID. Global shuffle: Lance with nothing downloaded is 1.1x to 1.7x faster than upstream reading local NVMe after the download. berkeley_rpt, toto and soarm101 are left out because their metadata lists frames the videos do not have; lerobot-lance-doctor reports that before you train.
- Faster iteration, end to end. 10,000 steps of SmolVLA on DROID, 8xH100, lerobot's default
num_workers=4, same seed:
| Lance, S3, nothing downloaded | upstream, local NVMe after a 384 GB download | |
|---|---|---|
| wall clock | 1 h 27 m | 2 h 00 m |
| steady rate | 495 samples/s | 361 samples/s |
| of each step spent waiting on data | 1.7% | 37.4% |
| final loss | 0.2380 | 0.2380 |
Same model, same loss, 33 minutes sooner, and no 384 GB download first. The difference is time the GPUs spend waiting on data, so it grows with the run: at 100k steps it is over five hours, and every re-run and sweep point pays it again.
- The training table is also the index. Parquet has no secondary indexes, so finding frames instead of scanning them usually means another system per question: a vector database for embeddings, a search service for instructions, a feature store for scores. With Lance those are columns and indexes on the same table the DataLoader reads. One query spans all of them, at a version the trainer can reopen.
Install
bash
pip install "lerobot[lancedb]"   # the reader, inside lerobot itself
pip install lerobot-lancedb      # the converter
Convert a dataset
Any LeRobot v3.0 dataset, from the Hub or a local directory:
bash
lerobot-lance-convert --repo-id lerobot/pusht --out ./pusht-lanceMigration costs about as much as a file copy. Videos are stored as blobs without re-encoding, so items are bit-identical to the source: 392,578 frames convert in 10 seconds, DROID's 27.6M in 34 minutes. Nothing about your recording or training code changes. The output keeps meta/ as is and adds three Lance tables (frames, videos, meta). lerobot-lance-doctor audits the result and often finds problems in the source: DROID carries 44% orphaned rows, and three of eight public datasets we converted have frame-count defects that only random access exposes.
Host the result anywhere: an HF dataset repo (hf upload, tag it v3.0), an HF Storage Bucket (hf buckets sync), or any object store (aws s3 sync).
Load and train
lerobot-lancedb provides one map-style dataset class for both image and video features, reading from a local path or an s3://, gs:// or hf:// URI with nothing downloaded up front. Pair it with lance_mp_context() so multi-worker DataLoaders share Lance's own multiprocessing context instead of the default one:
python
from lerobot_lancedb import LanceDBDataset, lance_mp_context
from torch.utils.data import DataLoader

dataset = LanceDBDataset(root="hf://datasets/lance-format/pusht-lance")
sample = dataset[0]
print(sample["observation.state"].shape)
print(sample["action"].shape)

loader = DataLoader(
    dataset,
    batch_size=32,
    num_workers=8,
    multiprocessing_context=lance_mp_context(),
)
Items are bit-exact with LeRobotDataset, and delta_timestamps configures temporal windows the same way.
Or from the CLI. Held-out evaluation on a remote dataset needs random access, so it only works on the Lance path:
bash
lerobot-train \
  --dataset.repo_id=my-org/my-bucket/pusht-lance \
  --dataset.repo_type=bucket \
  --dataset.eval_split=0.02 \
  --policy.type=act
Visualize TB-scale datasets in Foxglove
LeRobot's dataset viewer can serve an episode to Foxglove over its WebSocket protocol (lerobot#4542), and with a Lance dataset it works wherever the data lives:
bash
lerobot-dataset-viz --repo-id lance-format/pusht-lance --episode-index 3 --display-mode foxgloveOpen the Foxglove app, connect to ws://localhost:8765, and scrub. Cameras, joint state and actions show up as topics you can lay out however you like:
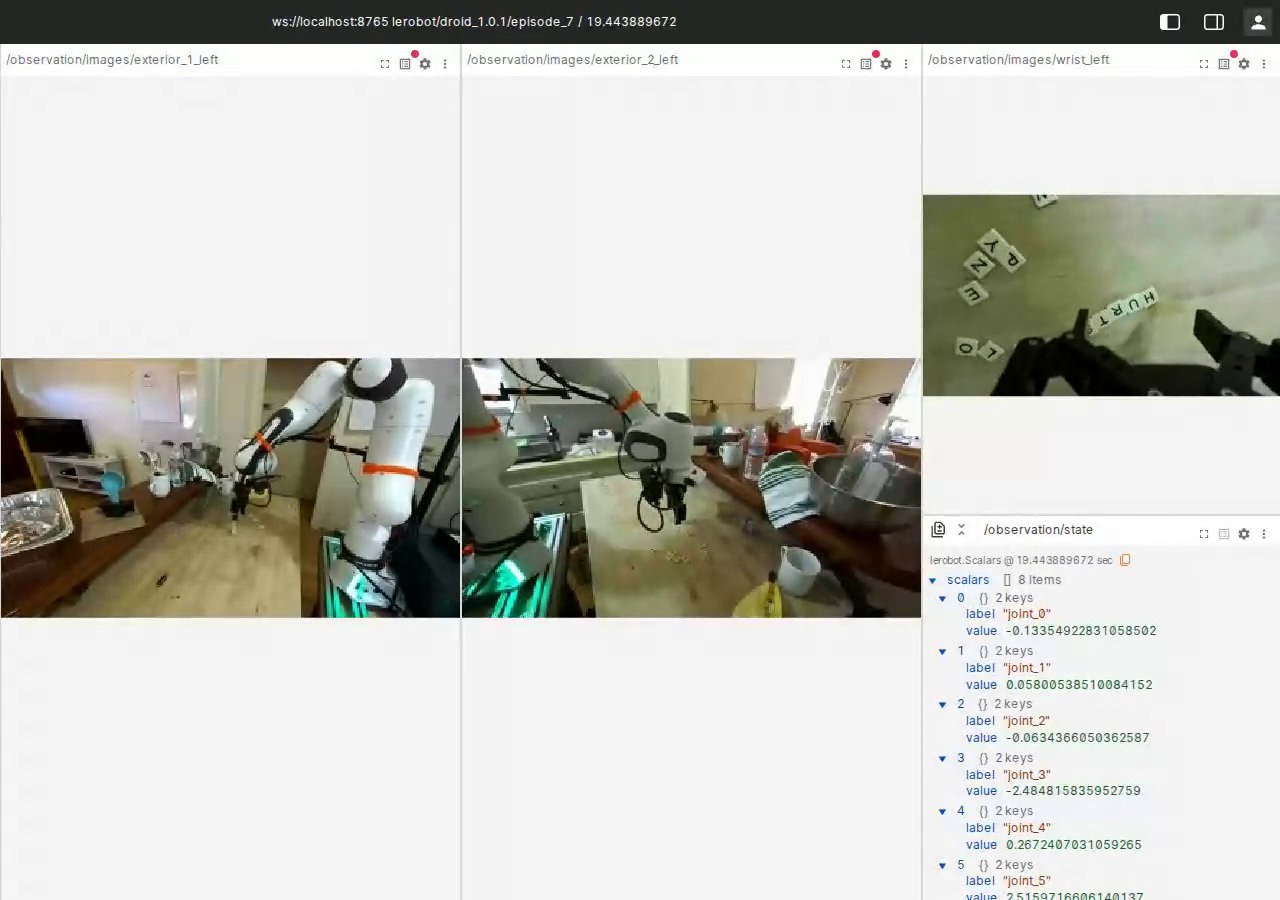
Frames are fetched as you scrub, so looking at one episode of the 373 GB DROID from S3 moves a few MB, not the dataset. No MCAP export, no download, and nothing new to install on the dataset side: this is the same reader the trainer uses.
Query, curate, enrich
The frames table is a LanceDB table like any other:
python
import lancedb

db = lancedb.connect("hf://datasets/lance-format/pusht-lance")
frames = db.open_table("frames")
videos = db.open_table("videos")

print(len(frames), len(videos))
print(frames.schema)
Filter with SQL over any feature, using the indexes built at conversion:
python
frame_rows = (
    frames.search()
    .where("episode_index = 0 AND frame_index < 10", prefilter=True)
    .select(["episode_index", "frame_index", "timestamp", "action"])
    .limit(10)
    .to_list()
)

for row in frame_rows:
    print(row["episode_index"], row["frame_index"], row["timestamp"])
From here it is standard LanceDB. The examples below are from our DROID walkthrough, all on the table the trainer reads.
Feature engineering costs nothing until you use it. With Geneva, add_columns registers a @udf function and its input columns as a new column and computes nothing; backfill computes and stores the values later, in parallel. No copy of the dataset, and the videos are never touched:
python
@udf(data_type=pa.float32(), input_columns=["action_joint_velocity"])
def jerk_score(v):                      # per-frame motion roughness
    ...

tbl.add_columns({"jerk_score": jerk_score})   # nothing computed yet
tbl.backfill("jerk_score", concurrency=8)     # 610,403 rows in 16.7 s
Embeddings work the same way, reading frames straight from the video blobs in the videos table:
python
@udf(data_type=pa.list_(pa.float32(), 768), num_gpus=1,
     input_columns=["episode_index", "frame_index"])
class EmbedFromBlob:                    # SigLIP2 loads once per worker
    def __call__(self, episode_index, frame_index):
        blob = self.videos.fetch_blob_files("video_bytes", [video_row_id])[0]
        frame = VideoDecoder(blob).get_frames_at([pos]).data[0]
        ...
Deduplication removes near-static runs before they skew curation or training. A stopped gripper holding one pose for a few seconds produces many frames whose emb_siglip2 vectors are nearly identical; LanceDB Enterprise's native dedupe collapses them into one representative per cluster, directly over the index, without a pairwise scan:
python
db.execute_query("""
    CREATE MATERIALIZED VIEW frames_deduped AS
    SELECT * FROM dedupe(
        'frames',
        'emb_siglip2',
        distance_threshold => 0.01
    )
""")
Every column survives the dedup unchanged -- jerk_score, the episode and camera metadata, the video blob reference -- since dedupe returns full rows, not just which ones matched. Wrap it in a materialized view, as above, to keep the deduplicated set current as new episodes land; see Materialized views.
Search is an index on those columns: a vector index over the embeddings built in 29.7 s across 27.6M rows, a full-text index over the instructions in 7.0 s, queries in 10 to 54 ms.
Curation is one query across all of it. Semantic search with a predicate on the derived score, no join, no second system:
python
results = (
    tbl.search(vec("a gripper closing on an object"), vector_column_name="emb_siglip2")
    .where("jerk_score > 1.2875")  # the roughest 1% of frames
    .limit(4)
    .to_arrow()
)
Mining is the same query pointed at the rare cases. tbl.search().where("jerk_score > 1.2875 AND success = false") pulls the rough, failed frames out of 27.6M rows in milliseconds, ready to become a fine-tuning set or a labeling queue.
EDA is a scan of the tabular columns: a pass over all 27.6M rows reads 2.52 GB in 190 s and decodes no video.
Then drop what you found from training with episodes=[...] instead of rewriting files. The reader ignores columns it does not know, and the table is versioned, so curation and training share one copy of the data at a version you can reopen.
说明
Lance datasets are read-only in LeRobot: record and edit in the default format, then convert.
Public examples to try everything above: lance-format/pusht-lance and friends under the lance-format org.